How I Built a Subtitle Pipeline for 106 TV Episodes with Whisper, Groq, and Python
TL;DR
- Whisper creates missing source subtitles before translation. I started with a self-hosted server and now use Groq-hosted Whisper, which was faster on my setup.
translate_subtitles.pysearches OpenSubtitles for Ukrainian subtitles first. It can correct a constant timing offset and uniform drift when the releases match.TRANSLATOR_CHAINsets the order of Google, MyMemory, LibreTranslate, Argos, and Claude CLI, including retries and timeout increases. Only unresolved cues move to the next step.- Each run skips existing outputs and logs its progress. The default acceptance threshold is 60 percent cue coverage, so a saved file can still contain English dialogue.
The job was bigger than translation
I had 106 episodes of The Fosters in .mkv format. Some came with an English .srt, some had no subtitle file at all, and a few had Ukrainian subtitles timed for a different release. I wanted one repeatable workflow that could handle all three cases without throwing away completed work.
That meant separating two jobs that are easy to blur together:
- Create a source-language SRT from the episode audio when no usable source subtitle exists.
- Produce the target-language SRT by finding, synchronizing, or translating subtitles.
translate_subtitles.py handles the second job. It does not invoke Whisper itself. The complete workflow uses a transcription helper first, then feeds the generated English SRT into the translation pipeline.
The obvious loop was not enough:
for line in subtitles:
    translated = translator.translate(line)
That loop says nothing about:
- creating timed source cues from audio when the episode has no SRT;
- finding an existing Ukrainian file before paying any translation cost;
- rejecting files mislabeled as Ukrainian;
- matching subtitle timing to a different release;
- falling back when a translator returns an empty or non-Cyrillic result;
- preserving progress across several runs.
The first missing stage was speech-to-text.
Stage 1: create the source SRT from audio
My first batch route ran whisper-asr-webservice on a server. The client connects over SSH, finds video files recursively, skips any video that already has a sibling SRT, and posts the rest to the server’s /asr endpoint.
export WHISPER_ASR_HOST="server.example.net"
export WHISPER_ASR_USER="media"
export WHISPER_ASR_SSH_KEY="$HOME/.ssh/id_whisper"
export WHISPER_LANGUAGE="en"

./whisper_batch.sh "/srv/media/The Fosters"
The self-hosted route had no per-request API fee, but it was slow on my hardware and its transcripts needed more correction than I wanted. I kept the script as an offline option, not as my default.
My current route is transcribe-groq.py. It extracts 16 kHz mono audio with FFmpeg, compresses it to Ogg Opus, splits long recordings into 25-minute chunks, calls Groq’s Whisper transcription endpoint, restores absolute timestamps, validates segment text and timing, and writes one SRT atomically. It preserves repeated dialogue and phrases that might be mistaken for hallucinations; those need human review. Existing output is protected unless I pass --force, and even then an empty or malformed result leaves the previous SRT intact.
export GROQ_API_KEY="your-api-key"

python3 transcribe-groq.py \
  "The Fosters S01E01.mkv" \
  --language en \
  --prompt "Character names: Lena, Stef, Callie, Jude"
The prompt is optional. I use it only for names and terms Whisper is likely to miss. The published version contains no personal prompt, local path, server address, login, or API key.
Both helpers are available beside the main script:
Neither route makes the source transcript correct by definition. Names, music captions, overlapping dialogue, and cuts at chunk boundaries still deserve a spot check before translation.
Groq receives the audio chunks. Google, MyMemory, and Claude receive subtitle text when their turn in the chain is reached; OpenSubtitles receives search metadata and authentication details for its own API. For private material, choose services whose data policies suit the content, or use self-hosted transcription and offline translation.
Once a source SRT exists, the rest of the workflow can make one decision per episode instead of one decision per cue.
The pipeline
For each episode, the two-stage workflow follows this order:
- Skip the episode if a
.uk.srtoutput already exists. - Create an English SRT from audio if no source subtitle exists.
- Search OpenSubtitles for a Ukrainian candidate.
- Reject candidates that fail basic language and structure checks.
- Fit a linear timing transform against the local English file.
- If no candidate survives, translate unique subtitle phrases through the fallback chain.
- Write the result and update both the structured run log and console log.
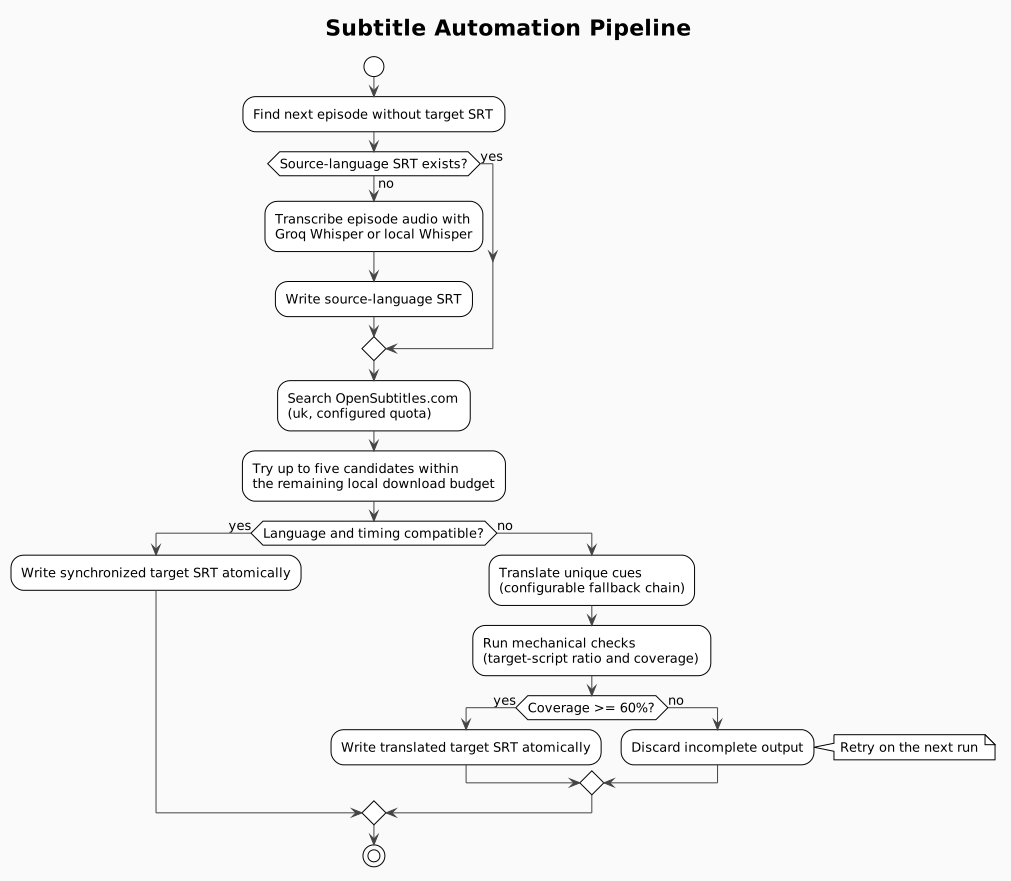
Finding a valid existing subtitle ends the job before any translator is called.
Search before translation
The script queries the OpenSubtitles API with the parsed series title, season number, episode number, and the configured target-language code. With the included preset, TARGET_LANGUAGE_CODE resolves to uk.
data = _os_get("/subtitles", {
    "query": title,
    "season_number": season,
    "episode_number": episode,
    "languages": TARGET_LANGUAGE_CODE,
})
OpenSubtitles quotas depend on the account and API consumer, so the local ceiling is configurable. The downloadable script defaults to 20. That value is configuration, not a promise: set OPENSUBTITLES_DAILY_LIMIT to the limit shown for your own account.
Credentials also belong outside the file:
OPENSUBTITLES_API_KEY      = os.environ.get("OPENSUBTITLES_API_KEY", "")
OPENSUBTITLES_ACCESS_TOKEN = os.environ.get("OPENSUBTITLES_ACCESS_TOKEN", "")
OPENSUBTITLES_USERNAME     = os.environ.get("OPENSUBTITLES_USERNAME", "")
OPENSUBTITLES_PASSWORD     = os.environ.get("OPENSUBTITLES_PASSWORD", "")
OS_DAILY_LIMIT = int(os.environ.get("OPENSUBTITLES_DAILY_LIMIT", "20"))
The script sends an API key for search and requires an authenticated session for its download path. That is a policy of this script: OpenSubtitles also documents a limited anonymous allowance. The script accepts OPENSUBTITLES_ACCESS_TOKEN directly or obtains a session token from the username and password at startup. It does not intentionally log credentials; review logs before sharing them.
Search results are not trusted just because their metadata says uk. The script samples the first 50 cues, checks that the text is mostly Cyrillic, and looks for Ukrainian-specific characters such as і, ї, є, and ґ. Russian-only characters such as ы, э, and ъ count against the candidate.
The guard now applies to actual /download attempts, not only accepted subtitles. A rejected candidate can still consume API quota, so every attempted download reduces the remaining local budget. Once it reaches zero, the script skips OpenSubtitles and continues with the translation chain.
Short samples, names, songs, and mixed-language dialogue can fool this filter. It does one useful job: it rejects many obviously mislabeled files before they reach the output directory. It does not prove that the remaining text is Ukrainian.
Once a candidate passes that check, timing becomes the next failure point.
Two points can fix drift, but not editing
Subtitle releases often disagree by a fixed start offset. Some also drift because the video was encoded at a different frame rate. A linear transform handles both effects:
new_time = scale * old_time + offsetThe script takes the first and last cue start times from the local English file and the downloaded Ukrainian file:
scale = (en_t1 - en_t0) / (uk_t1 - uk_t0)
offset = en_t0 - scale * uk_t0
It then rejects suspicious matches:
- the cue counts may differ by no more than 20 percent;
scalemust stay within 10 percent of1.0;- the first five transformed cue starts must remain within two seconds of their English counterparts.
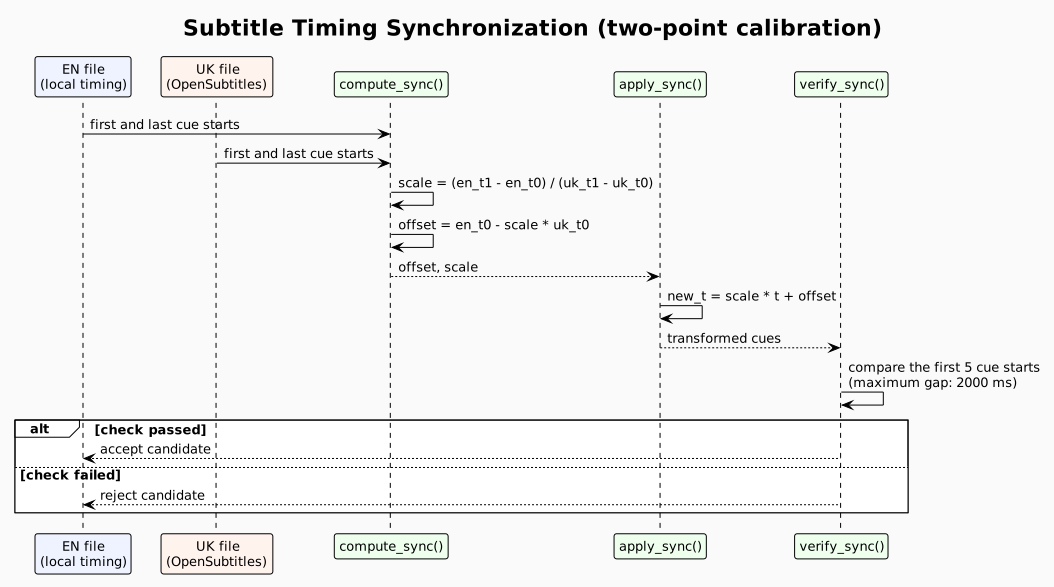
This works when the first and last cues refer to the same moments and the mismatch is approximately linear. It fails when one release adds a recap, removes captions, splits dialogue differently, or inserts an extra scene. A stronger synchronizer would match cue content or audio landmarks instead of assuming correspondence by index.
When no compatible Ukrainian file exists, the pipeline finally translates.
A configurable Chain of Responsibility
The chain is configured at the top of the script:
TRANSLATOR_CHAIN = (
    "Google (2:30) -> MyMemory (1:10) -> "
    "LibreTranslate (1:20) -> Argos -> Claude"
)
Any registered service can move to any position in TRANSLATOR_CHAIN. The parser skips unavailable services and uses the first remaining service for the primary batch. The linked fallback chain follows the same order.
“Available” is deliberately a local setup check, not a live health check. The script verifies that the required Python package, Argos language model, LibreTranslate URL, or claude executable exists. A configured service can still time out later, which is why runtime failures continue through the same chain.
For example, I can switch to an offline-first setup without changing translate_file():
TRANSLATOR_CHAIN = "Argos -> Google (3:20) -> Claude"Argos receives the primary batch in this configuration. The settings move with each service: Google (3:20) means one attempt plus three retries, with 20 seconds added to the timeout for each retry. A service without parentheses gets one attempt and no retry.
For the primary service, the batch pass is that first attempt. If its configuration says Google (2:30), failed cues get two more Google attempts at 60 and 90 seconds before moving to MyMemory. The primary service is not repeated at the base timeout when the linked chain begins.
The timeout applies per Google chunk of up to 20 cues, per MyMemory chunk of up to 5 cues, per LibreTranslate HTTP request, and per Claude subprocess. A whole batch can take longer. Google and MyMemory workers are terminated when their deadline expires, and completed chunks are retained. The offline Argos backend does not enforce this timeout.
Only unresolved cues enter the linked chain, so a timeout or empty response does not restart the whole file. A malformed step or unknown service stops the script at startup instead of silently changing the route.
The pattern itself is small. Each step handles the entries it can and passes the remaining entries to self.next:
class TranslatorStep:
    def __init__(self, name, fn, fallbacks=0, timeout_inc=0, timeout_base=30):
        self.name = name
        self.fn = fn
        self.fallbacks = fallbacks
        self.timeout_inc = timeout_inc
        self.timeout_base = timeout_base
        self.next = None

    def set_next(self, step):
        self.next = step
        return step

    def execute(self, entries, attempts_already_used=0):
        remaining = entries

        total_attempts = self.fallbacks + 1
        for attempt in range(attempts_already_used, total_attempts):
            if not remaining:
                return

            timeout = self.timeout_base + attempt * self.timeout_inc
            result = self.fn(remaining, timeout=timeout)
            remaining = [
                (idx, text) for idx, text in remaining
                if not (
                    result.get(idx)
                    and target_script_ratio(result[idx]) >= MIN_QUALITY
                )
            ]

        if remaining and self.next:
            self.next.execute(remaining)
The chain is built from the configuration rather than hardcoded conditionals:
steps = [
    TranslatorStep(
        name=step['name'],
        fn=_FN_MAP[step['name']],
        fallbacks=step['fallbacks'],
        timeout_inc=step['timeout_inc'],
    )
    for step in resolved
]

for index in range(len(steps) - 1):
    steps[index].set_next(steps[index + 1])

steps[0].execute(needs_retry, attempts_already_used=1)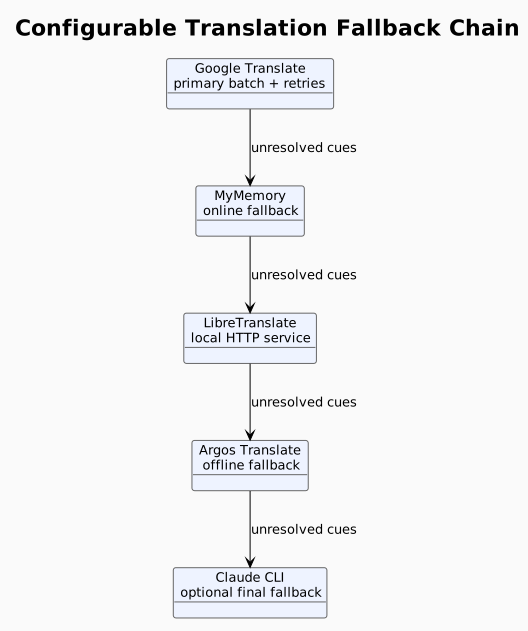
Why this order?
- Google is the primary pass because it produced the best dialogue in my tests. The script accesses it through
deep-translator, whose Google backend uses the web client rather than the official paid API. - MyMemory provides a second online route when Google leaves a line untranslated.
- LibreTranslate runs as a local HTTP server. It has no per-request fee and keeps the request on my machine, but its output for this series was not good enough to make it the primary translator.
- Argos Translate works offline and has no request quota, but its Ukrainian output was often too literal for TV dialogue.
- Claude CLI runs last. The script launches it as a subprocess only after the other backends leave cues unresolved.
This was the difference I saw when comparing the offline model with Google on real dialogue:
| Original | Argos | |
|---|---|---|
| “I’m sorry” | “Я шкода” | “Вибачте” |
| “Previously on The Fosters” | “Попередньо на піни” | “Раніше у Фостерів” |
These samples explain my choice of default order; they are not a benchmark across languages or genres.
A sanity check, not a translation review
The pipeline calculates the share of alphabetic characters that use the configured target script. With the Ukrainian preset, that means Cyrillic:
def target_script_ratio(text):
    alpha = re.findall(ALL_LETTERS_PATTERN, text)
    if not alpha:
        return 1.0
    target_letters = re.findall(TARGET_SCRIPT_PATTERN, text)
    return len(target_letters) / len(alpha)
A result below 70 percent is sent to the next translator. If fewer than 60 percent of translatable cues receive an accepted result, the output file is discarded and retried during a later run.
At 60 percent coverage or above, the script saves the file and leaves unresolved cues in their original English. For example, a file with 100 translatable cues can be accepted with 60 translated cues and 40 still in English. File discovery then skips that .uk.srt on the next run; it does not retry the missing translations inside it. I need to review partial outputs manually. To translate the episode again, I can move its output outside subtitles_output/ and rerun with the source file still in place.
For the included English-to-Ukrainian configuration, this catches empty responses, untranslated English, and some malformed batches. It cannot detect bad grammar, lost context, wrong names, invented meaning, or awkward Ukrainian. The ratio is a mechanical sanity check, not a translation quality score.
Formatting needs the same caution. The script preserves a single outer HTML-style tag, but nested tags can be lost, and multi-line cues are flattened before translation. If styling and line breaks matter, they should be replaced with placeholders before translation and restored from a token map afterward.
Once a line passes the mechanical check, the remaining problem is operational: a 106-file job still has to survive interruption.
Resuming and logging without starting over
Every accepted output ends with .uk.srt. File discovery skips an existing target path, including a partially translated file, and schedules only missing outputs.
subtitles_source/
  Season 1/
    The Fosters S01E01.en.srt

subtitles_output/
  Season 1/
    The Fosters S01E01.uk.srt
The script keeps two different logs. Log_console.txt opens in append mode and mirrors everything printed to stdout: resolved chain, batch progress, retries, errors, and the final summary. It is the file I inspect when a backend fails halfway through an episode.
Log.md is the compact run history. The script prepends a timestamped row after every processed file and writes another row if I stop it with Ctrl+C. Each row records completed files, OpenSubtitles download attempts, per-translator phrase counts, failed episodes, the local OpenSubtitles balance, and the externally supplied Claude usage estimate.
This is a real checkpoint from the first long run, trimmed to the columns relevant here:
| 2026-03-29 05:48:59 | 25/88 complete | Google×19,408 | MyMemory×21 | LibreTranslate×44 | Claude×17 |The full row also contains a machine-readable [OS:n] suffix with only the new download attempts since the preceding checkpoint. At startup, count_today_os_downloads() sums today’s tags so separate runs share the same local daily ceiling without counting the same attempt twice.
Each SRT is first written to a sibling temporary file. Once all cues have been written and the file flushed, os.replace() moves it to the final path. This protects the write from interruption; accepted cue coverage determines whether the script keeps the output.
Launching Claude CLI for the remaining lines
The script does not call the Anthropic API directly. It launches the installed Claude CLI as a subprocess for unresolved cues:
with tempfile.TemporaryDirectory(prefix="subtitle_claude_") as workdir:
    result = subprocess.run(
        [
            "claude", "--print", "--output-format", "text", "--model", CLAUDE_MODEL,
            "--tools", "", "--strict-mcp-config", "--mcp-config", '{"mcpServers":{}}',
            "--disable-slash-commands", "--setting-sources", "", "--no-session-persistence",
        ],
        input=prompt,
        capture_output=True,
        text=True,
        timeout=timeout,
        cwd=workdir,
    )
Each chain attempt launches the CLI once, with the chain’s timeout. The CLI runs in an empty temporary directory with tools, MCP servers, slash commands, and session persistence disabled by these flags. Subtitle text still goes to the selected online provider; these settings do not make cloud translation private or offline.
Before launching it, the script reads CLAUDE_USAGE_FILE only if I explicitly set it. An external process must supply a JSON file such as {"remaining_percent": 75} and refresh it as usage changes. The value must be a number from 0 to 100, and the file must have been modified within the last five minutes. The script does not fetch account usage or inspect Claude history.
export CLAUDE_USAGE_FILE="./claude-usage.json"
python3 translate_subtitles.py 10 --min-tokens 30
This is an external estimate, not an authoritative quota check. A missing, stale, or invalid file means usage is unknown. The script then skips Claude unless I explicitly use --min-tokens 0 to disable the guard. A separate writer should update the file atomically; a fixed example value is not a useful quota monitor.
def claude_allowed(min_pct: float) -> bool:
    if _token_pct is None:
        return min_pct == 0
    return _token_pct >= min_pct
The Claude CLI reference documents these flags. Use a CLI version that supports them; an unsupported invocation fails and leaves its cues unresolved.
Configuration reference
Language pair and validation
This article uses English source subtitles and Ukrainian output, but that is a preset rather than a hardcoded route. The OpenSubtitles search, online translators, Argos package lookup, Claude prompt, and output filenames read these settings:
SOURCE_LANGUAGE_CODE   = "en"
SOURCE_LANGUAGE_NAME   = "English"
SOURCE_LANGUAGE_LOCALE = "en-US"
SOURCE_INPUT_SUFFIX    = "en"

TARGET_LANGUAGE_CODE   = "uk"
TARGET_LANGUAGE_NAME   = "Ukrainian"
TARGET_LANGUAGE_LOCALE = "uk-UA"
TARGET_OUTPUT_SUFFIX   = "uk"
The language validator is a separate part of the configuration:
ALL_LETTERS_PATTERN               = r'[a-zA-Zа-яА-ЯіІїЇєЄґҐ]'
TARGET_SCRIPT_PATTERN             = r'[а-яА-ЯіІїЇєЄґҐ]'
TARGET_LANGUAGE_MARKERS_PATTERN   = r'[іІїЇєЄґҐ]'
REJECTED_LANGUAGE_MARKERS_PATTERN = r'[ыЫэЭъЪ]'
To adapt the script, change both groups. For English-to-German, for example, set the four TARGET_* values to de, German, de-DE, and de; use a Latin-letter pattern for both ALL_LETTERS_PATTERN and TARGET_SCRIPT_PATTERN; and set both marker patterns to empty strings. English and German share a writing system, so the character-ratio check can no longer detect untranslated English. The pipeline still runs, but that particular guard becomes a structure check rather than a language check.
If the audio language also changes, pass its ISO-639-1 code to transcribe-groq.py --language or set WHISPER_LANGUAGE for whisper_batch.sh. Then update all four SOURCE_* values in translate_subtitles.py to match the generated source files.
Backend support is the remaining constraint. Argos needs a package for the selected pair, and each online service must support both language codes.
Runtime settings
The runtime defaults sit directly below the language block:
OPENSUBTITLES_API_KEY      = os.environ.get("OPENSUBTITLES_API_KEY", "")
OPENSUBTITLES_ACCESS_TOKEN = os.environ.get("OPENSUBTITLES_ACCESS_TOKEN", "")
OPENSUBTITLES_USERNAME     = os.environ.get("OPENSUBTITLES_USERNAME", "")
OPENSUBTITLES_PASSWORD     = os.environ.get("OPENSUBTITLES_PASSWORD", "")
OPENSUBTITLES_APP_NAME     = "SubtitleTranslator/1.0"

BATCH_SIZE          = 80
CLAUDE_MODEL        = "claude-haiku-4-5-20251001"
DELAY_BETWEEN_CALLS = 0.4
MAX_FILES_PER_RUN   = 30
MIN_QUALITY         = 0.70
MAX_SYNC_GAP_MS     = 2000
MAX_SYNC_DRIFT      = 0.10
OS_DAILY_LIMIT      = int(os.environ.get("OPENSUBTITLES_DAILY_LIMIT", "20"))
MIN_TOKENS_PCT = 30| Setting | What it controls |
|---|---|
OPENSUBTITLES_API_KEY |
Reads the OpenSubtitles consumer key from the environment. With no key, the script skips the OpenSubtitles stage. |
OPENSUBTITLES_ACCESS_TOKEN |
Accepts an existing Bearer token for authenticated downloads. |
OPENSUBTITLES_USERNAME, OPENSUBTITLES_PASSWORD |
Let the script request a session token at startup when no access token was supplied. They are never printed or written to the log. |
OPENSUBTITLES_APP_NAME |
Sends the User-Agent value required by OpenSubtitles requests. |
BATCH_SIZE |
Limits how many unique subtitle phrases the primary translator receives in one batch. |
CLAUDE_MODEL |
Supplies the value passed to claude --model when the final fallback runs. |
DELAY_BETWEEN_CALLS |
Adds a pause between translation batches and selected OpenSubtitles requests. |
MAX_FILES_PER_RUN |
Caps one run at 30 files by default. The positional CLI argument overrides it. |
MIN_QUALITY |
Sets the minimum target-script ratio accepted from any translator in the chain. It is a format sanity check, not a language-quality score. |
MAX_SYNC_GAP_MS |
Rejects a synchronized candidate when one of the first five cue starts differs from the English file by more than 2000 ms. |
MAX_SYNC_DRIFT |
Restricts the timing scale to 1.0 ± 0.10, which filters out likely mismatched releases. |
OS_DAILY_LIMIT |
Sets the script’s local OpenSubtitles download ceiling. OPENSUBTITLES_DAILY_LIMIT overrides the default. |
MIN_TOKENS_PCT |
Prevents Claude CLI from running below the externally supplied remaining-usage percentage. --min-tokens overrides it for one run. |
CLAUDE_USAGE_FILE |
Optional environment variable pointing to a JSON file with remaining_percent (0–100), refreshed externally within five minutes. Unknown usage blocks Claude unless the threshold is zero. |
TRANSLATOR_CHAIN |
Defines the backend order and the per-service fallbacks:timeout_inc values. |
LIBRETRANSLATE_URL |
Enables the local LibreTranslate step when the environment variable contains a server URL. |
LIBRETRANSLATE_URL is also read from the environment. Leaving it empty removes LibreTranslate from the resolved chain; setting it to a local server URL enables the step without changing TRANSLATOR_CHAIN.
Setup
The Python scripts require Python 3.10+ on macOS or Linux. The self-hosted batch helper uses SSH and expects Bash, GNU find/sort, and curl on the server.
For the Groq transcription route, install ffmpeg and make sure both ffmpeg and ffprobe are on PATH. The Python helper itself uses only the standard library.
export GROQ_API_KEY="your-api-key"
python3 transcribe-groq.py "episode.mkv" --language en
The local route requires an SSH-accessible whisper-asr-webservice instance. Its host, user, port, key path, and source language all come from environment variables shown earlier; none is embedded in the downloadable script.
For the translation stage, create a virtual environment instead of modifying the system Python installation:
python3 -m venv .venv
source .venv/bin/activate
python -m pip install deep-translator argostranslate
Set the API key, account credentials, and the quota that applies to your OpenSubtitles account. You may supply OPENSUBTITLES_ACCESS_TOKEN instead of the username and password if you already have a valid token.
export OPENSUBTITLES_API_KEY="your-api-key"
export OPENSUBTITLES_USERNAME="your-username"
export OPENSUBTITLES_PASSWORD="your-password"
export OPENSUBTITLES_DAILY_LIMIT="20"
Optional local services:
# Argos package index and the default English-to-Ukrainian model
argospm update
argospm install translate-en_uk

# LibreTranslate
docker run --rm -p 127.0.0.1:6455:5000 libretranslate/libretranslate
export LIBRETRANSLATE_URL="http://127.0.0.1:6455"
The Argos Translate repository and LibreTranslate installation guide are the better source for current installation details.
Then place English subtitle files under subtitles_source/ and run:
python3 translate_subtitles.py       # up to 30 files
python3 translate_subtitles.py 10    # up to 10 files
python3 translate_subtitles.py --debug-tokens
Download the scripts used by the two-stage workflow:
- Translate, synchronize, and resume the batch
- Transcribe one audio or video file through Groq Whisper
- Transcribe a remote media directory through a self-hosted Whisper server
Results from the first run
The 106 episodes in the title are the size of my collection. The first long translation run covered 88 pending episode files and had saved 25 outputs by the early-morning checkpoint shown above. That is the progress recorded here, not a final completion count for all 106 episodes. The excerpt does not establish the status of the other 18 episodes.
Here, “complete” in the checkpoint means the script accepted and saved an output. With the 60 percent threshold, some accepted files can still contain English cues. Subsequent runs skip those files too.
OpenSubtitles contributed no completed file to that run. Searches returned candidates, but the /download requests returned HTTP 403. I suspected the original authentication flow, although that status alone does not establish the cause. The downloadable version uses an explicitly authenticated download path: it logs in from environment-provided credentials or accepts an access token, adds Authorization: Bearer ..., and skips downloads when authentication is unavailable.
Most cues never reached Claude CLI because an earlier backend handled them. The actual mix changed from episode to episode depending on which subtitles already existed and which services were available.
The script reports accepted cue coverage, not linguistic quality. A file with 100 percent coverage can still contain awkward wording, so the percentage should be read as “every cue received an accepted result”, not “every translation is correct”.
Current limitations
I would still change seven things before treating this as a general-purpose subtitle tool:
- Review names and chunk boundaries in Whisper-generated source files before translation.
- Match OpenSubtitles results by IMDb or TMDB identity, not title text alone.
- Detect subtitle encoding instead of decoding every download as UTF-8 with replacement.
- Preserve nested tags and line breaks with placeholders.
- Replace index-based timing verification with cue-text or audio landmark matching.
- Replace character-ratio validation with language identification when source and target share an alphabet.
- Add integration fixtures for transcription boundaries, constant offset, uniform drift, and a deliberately incompatible subtitle release.
The next hard problem is proving that a subtitle is correct without watching all 45 minutes. Adding translator number six will not solve that.
Discussion
Comment translation
No languages found.